● OmniFysics-Nano-V2 Technical Report: Understanding the Physical World Across Modalities
Yizhou Liu, Jinghang Han, Kaixiang Qiu, Qi He, Minghao Han, Yue Jiang, Xujia Chen, Wei Zou, Shunli Wang*, Lihua Zhang*, Dingkang Yang*
ArXiv
Omni-modal models have expanded multimodal interaction across vision, audio, speech, and language.
However, their training is predominantly organized around semantic descriptions and general-purpose
objectives, leaving physical attributes, interaction states, and causal mechanisms only partially specified.
This gap is not simply a matter of modality coverage: adding more modalities does not by itself provide
the supervision needed to connect observations with the physical structure of the world. We present
OmniFysics-Nano-V2, a compact omni-modal model for physical-world perception and understanding.
The model supports image, video, audio, speech, and text inputs within a shared reasoning framework,
together with text and speech generation. To address the lack of explicit physical supervision, we construct
a dual-branch physics-aware data pipeline that grounds salient objects in structured physical attributes
and aligns visual changes with acoustic events, intermediate responses, and interaction outcomes. To
address homogeneous training objectives, we curate reinforcement-learning prompts by reward diversity
and adopt a two-stage Group Relative Policy Optimization curriculum that progresses from general task
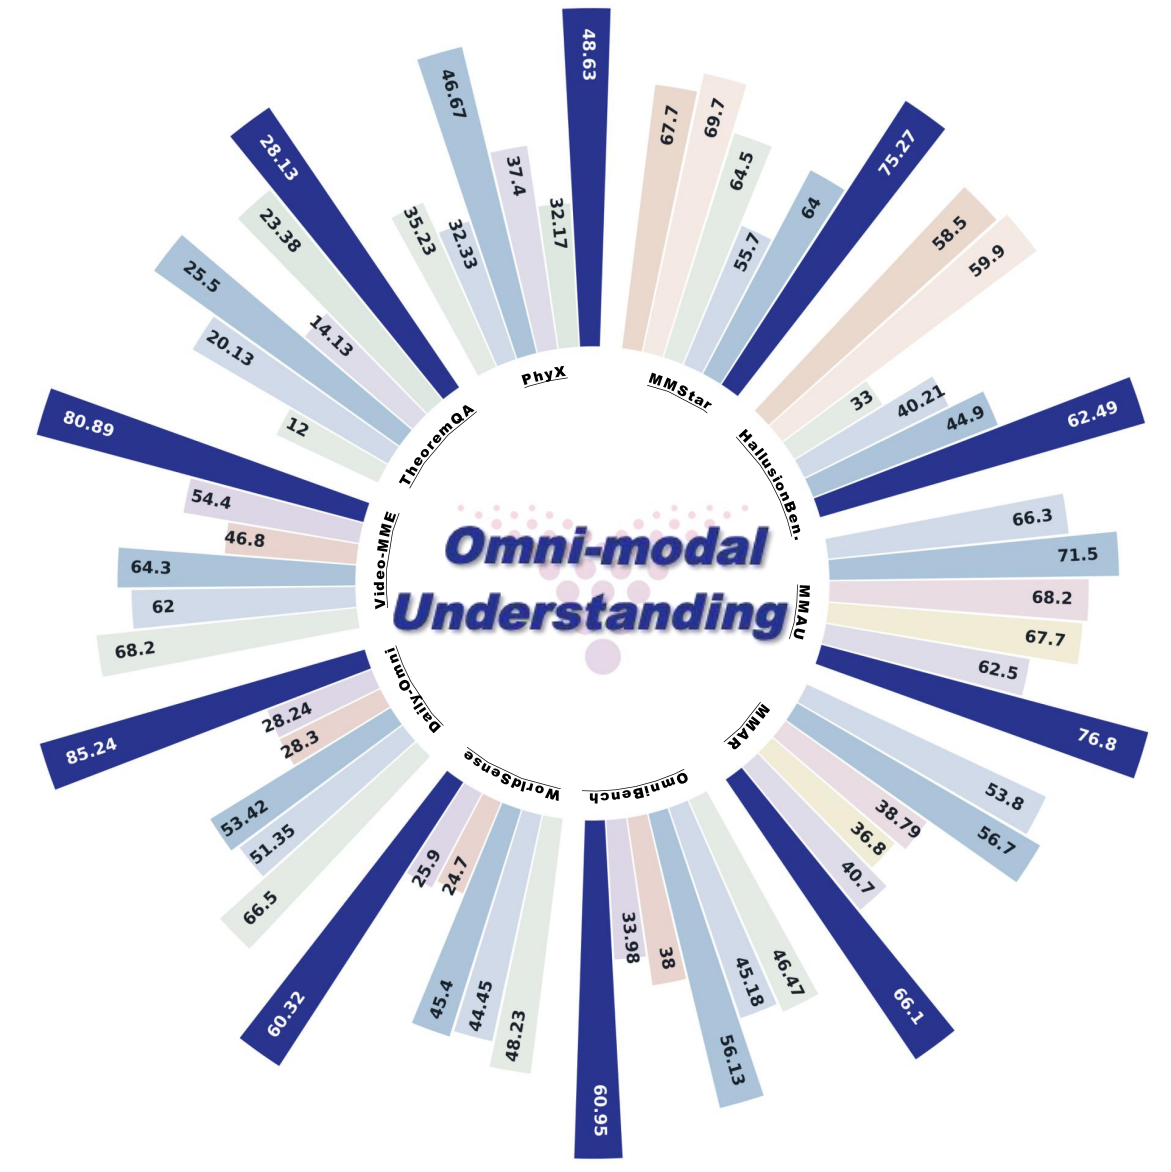
correctness to fine-grained physical perceptual reasoning. Experiments across multimodal, audio-visual, and
physical reasoning benchmarks show that the proposed data and training strategy improves physical-world
understanding while preserving broad omni-modal competence. The proposed model achieves leading result
on 17 of 21 benchmarks against SOTA omni-modal models. By equipping AI systems with both omni-modal
and physical-world perception capabilities, OmniFysics-Nano-V2 is poised to become a cornerstone of
next-generation Physical AI.